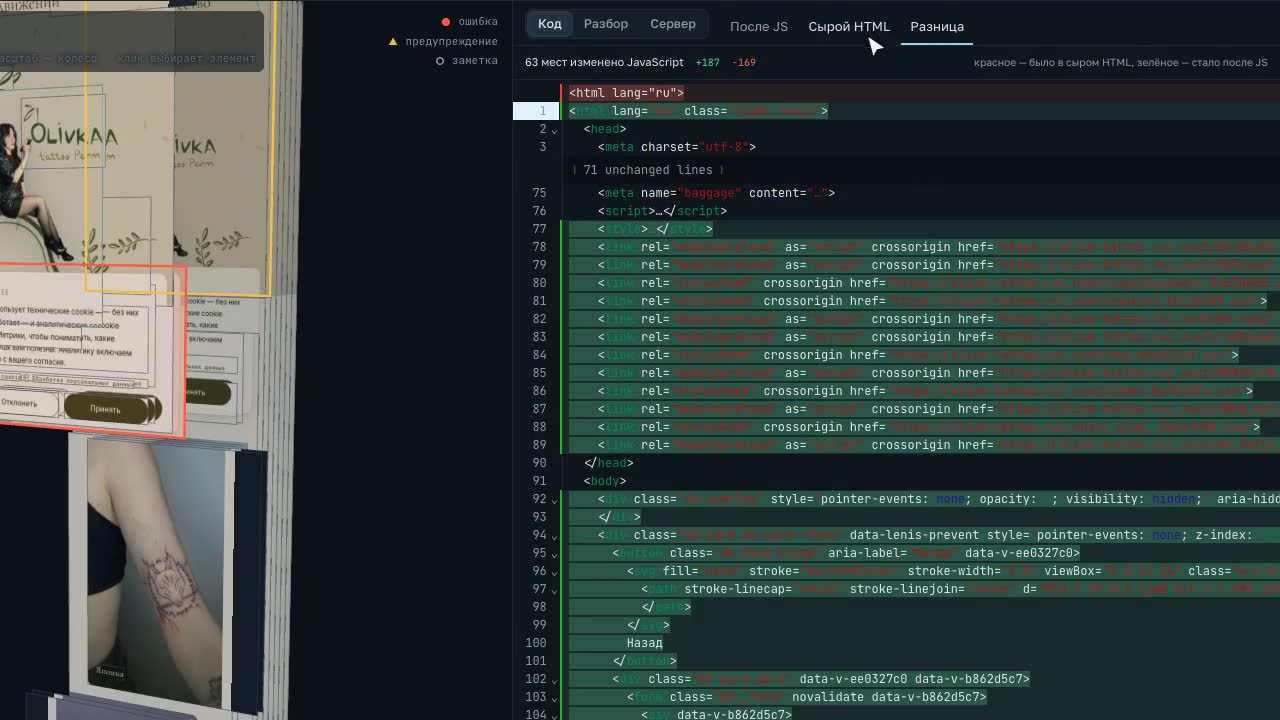
Raw vs rendered
What ChatGPT sees vs what Google sees
Raw HTML is what GPTBot, ClaudeBot and PerplexityBot read. Rendered HTML is what Googlebot indexes. The Diff tab puts them side by side, line by line.
Googlebot · GPTBot · ClaudeBot · PerplexityBot
Rendering, indexing, W3C, structured data and speed — every problem highlighted right on the page, in a 3D cross-section of its DOM.
Free during beta · interface in Russian for now
example.com/catalog
1,204 elements · render 3.2 s
● Googlebot · sees the full page
● AI crawlers · empty catalog
AI crawlers read your page without JavaScript. The app shows exactly that: a no-JS 3D view, a raw vs rendered diff and an AI crawlers tab.
olive-tattoo.rua real check
A recording of a real check of a live site, sped up.Interface in Russian during beta.
Raw vs rendered
Raw HTML is what GPTBot, ClaudeBot and PerplexityBot read. Rendered HTML is what Googlebot indexes. The Diff tab puts them side by side, line by line.
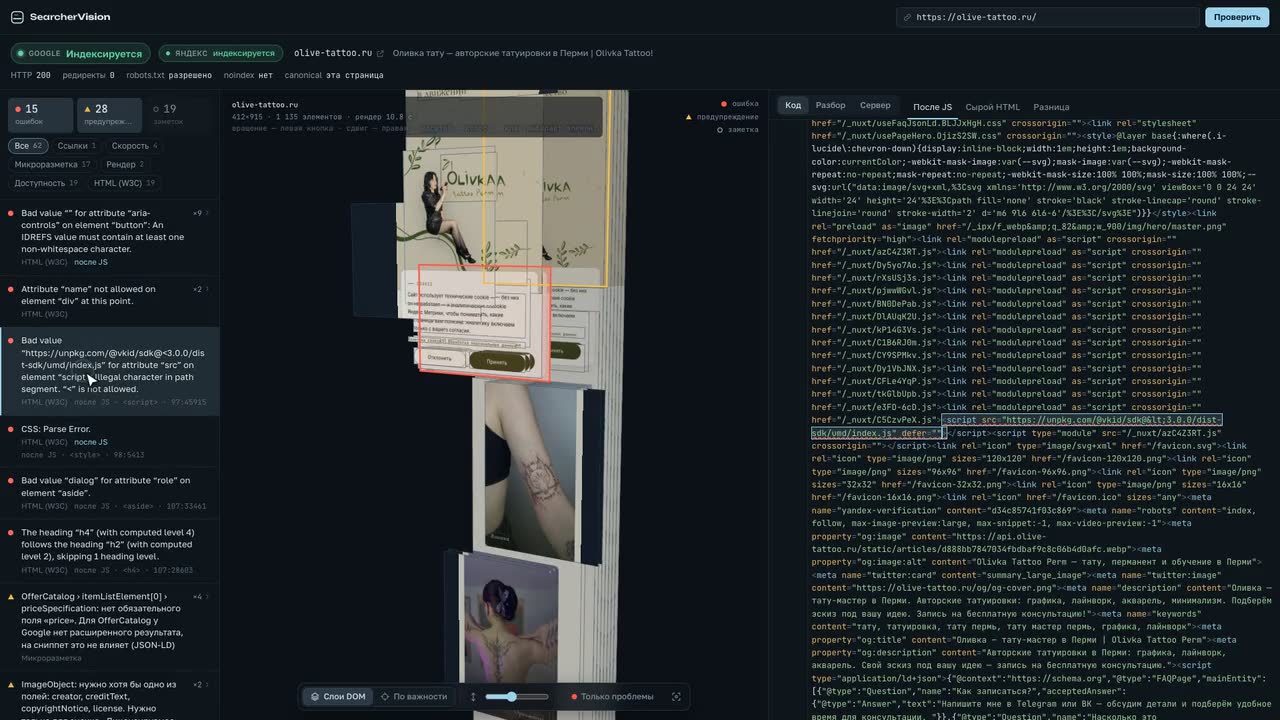
Report
Hover a problem in the list and the element lights up in the 3D cross-section. Pick one and the source opens at the exact line.
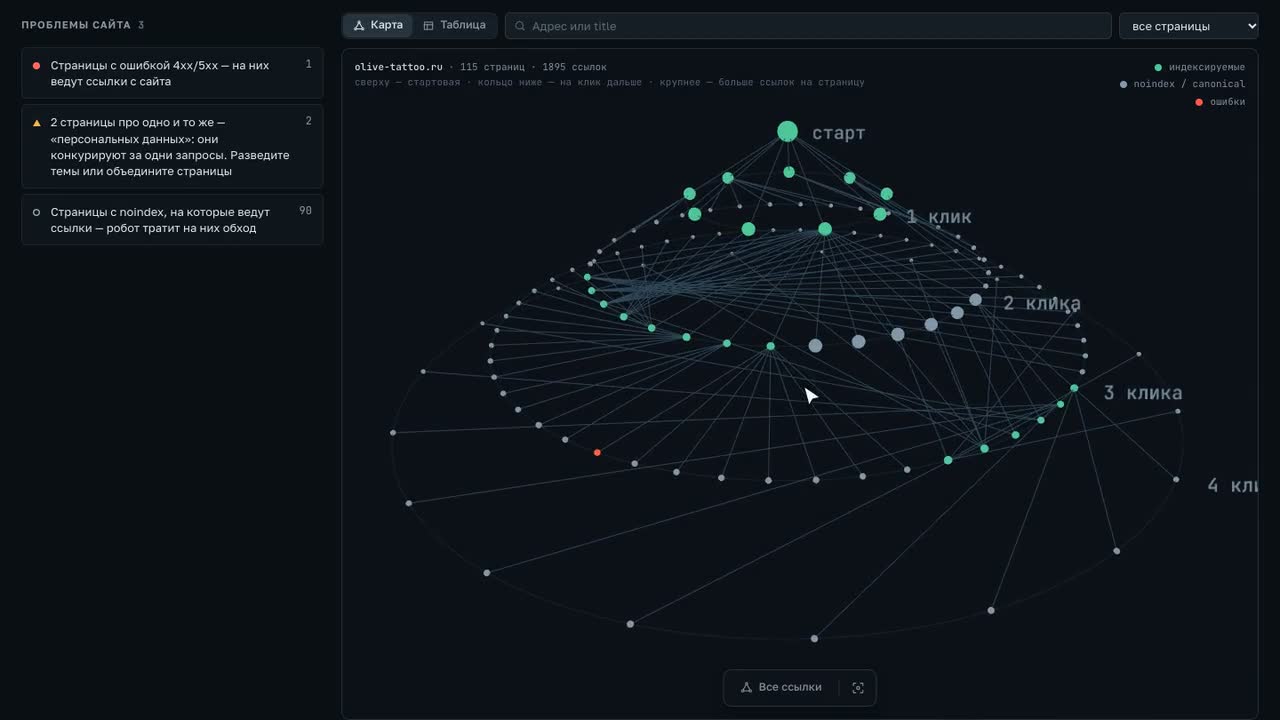
Site crawl
Breadth-first from the homepage, like Googlebot. Pages sit on rings of click depth, color shows whether they’re indexable, and a site issue lights up its pages.
raw HTMLafter JavaScriptGooglebot · AI crawlers
The page looks fine in a browser, but crawlers get something else. Four cases SearcherVision finds and points to in the code.
raw HTML14 lines
<body>
  <div id="app"></div>
  <script src="/app.js"></script>
</body>
after JavaScript+318 lines
<h1>Sofas & armchairs</h1>
<p>Delivered in 2 days…</p>
▲ main text appears only after JavaScript
Googlebot renders it. GPTBot, ClaudeBot and PerplexityBot never do — to them, that text isn’t there.
JSON-LD · FAQPage1 of 4 questions
{
  "@type": "Question",
  "name": "How much is delivery?",
  "acceptedAnswer": {
    "text": "Free on orders over $300"
  }
}
▲ the answer isn’t in the page text
Google requires marked-up content to be visible. We check every answer against the page text.
<head>line 12
<meta name="yandex" content="noindex">A header or meta tag that hides the page from one search engine and not the other.
after JavaScript<nav>
<nav>
  <a href="/catalog/chairs">Armchairs</a>
  <a href="/catalog/sofas">Sofas</a>
</nav>
▲ this link isn’t in the raw HTML
Crawlers that don’t render will never follow them.
GooglebotGPTBotClaudeBotPerplexityBot
Googlebot renders JavaScript before indexing. AI crawlers — the ones behind ChatGPT, Claude and Perplexity — read only the raw HTML. SearcherVision shows both versions of your page and the exact difference between them.
Googlebot/2.1 · renders in Chromium
●Sees the full page
GPTBot · ClaudeBot · PerplexityBot
●Sees an empty catalog
See exactly what exists only after JavaScript — the part AI assistants never read.
Who is allowed in: GPTBot, ClaudeBot, PerplexityBot, Google-Extended — and whether the server really lets them through.
For sites in Russia and CIS — a separate Yandex verdict.
What we checkdeterministic rules
Every check is deterministic. Each problem points to a line and column in the source and to the element in the 3D cross-section.
Method: Googlebot Smartphone and YandexBot user agents
Method: Chromium · Playwright
Method: Nu Html Checker — the validator.w3.org engine
Method: schema.org vocabulary · Google rich result rules
Method: Chromium · PageSpeed Insights
Method: Deterministic rules: every issue has a place in the code
breadth-first crawlup to 1,000 pages
Breadth-first from the start page, like Googlebot: up to 1,000 pages from raw HTML or 300 with rendering. Broken pages and who links to them, redirects, duplicate titles, orphans, sitemap gaps, keyword cannibalization — on a 3D map of click depth.
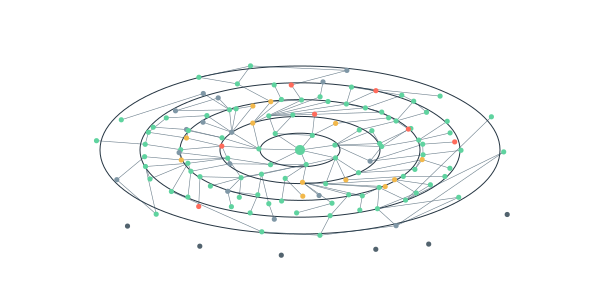
example.com · 134 pages
raw HTML crawl · 41 s
rings — clicks from the homepage
MCPStreamable HTTP
Connect SearcherVision to Claude Code, Cursor or any MCP client. The agent checks a page and gets every problem with its position in the code — then fixes it.
Server address: https://api.searchervision.com/mcp
Claude Code · setup
claude mcp add --transport http searcher-vision https://api.searchervision.com/mcpCheck the homepage and fix the markup errors
searcher-vision · analyze_page(https://example.com/)
Google: indexable · Yandex: indexable
Problems: 3 errors, 5 warnings, 12 notes

Errors:
- [HTML (W3C)] Bad value "dialog" for attribute "role"
  after JS 107:33498 <aside> cid=412
- [Structured data] Product › offers: "price" is missing
raw HTML 41:5get_html(cid=412) → editing components/Sidebar.vue
Pricing
Use SearcherVision free while it’s in beta. Pro and Agency are in development — join the list for early access.
$0
Works today, no sign-up.
$19/mo
For people who check sites every day.
from $99/mo
For teams that run client sites.
Prices are a hypothesis — join the list and tell us what you’d pay for.
FAQPagemarkup matches the text
The answers on this page and in its structured data match word for word — exactly what SearcherVision checks for FAQ markup.
Search Console shows only your own verified sites and only Google. SearcherVision checks any URL, shows Google and AI crawlers side by side, and points to the exact element in the code.
No. Any public URL works.
We emulate crawlers from our server. Geo rules and bot protection see our server, not Google. Search Console integration (coming in Pro) adds Google’s own data.
GPTBot, ClaudeBot and PerplexityBot fetch raw HTML and don’t execute JavaScript, according to Vercel’s analysis of their traffic. Google-Extended is the exception: it uses Google’s rendering.
40 checks per hour and 6 crawls per day per IP during beta.
We started in Russia and CIS. The English interface is next — join the list and we’ll tell you when it’s ready.